


Persistent, local-first memory for AI agents. Engraphis stores scoped project knowledge, retrieves relevant evidence across vector, lexical, graph, and code search, and returns bounded context with sources an agent can inspect.
The local engine uses SQLite and works offline. It keeps changes over time instead of silently replacing facts, and grounded recall cites retrieved memories or abstains when evidence is weak.
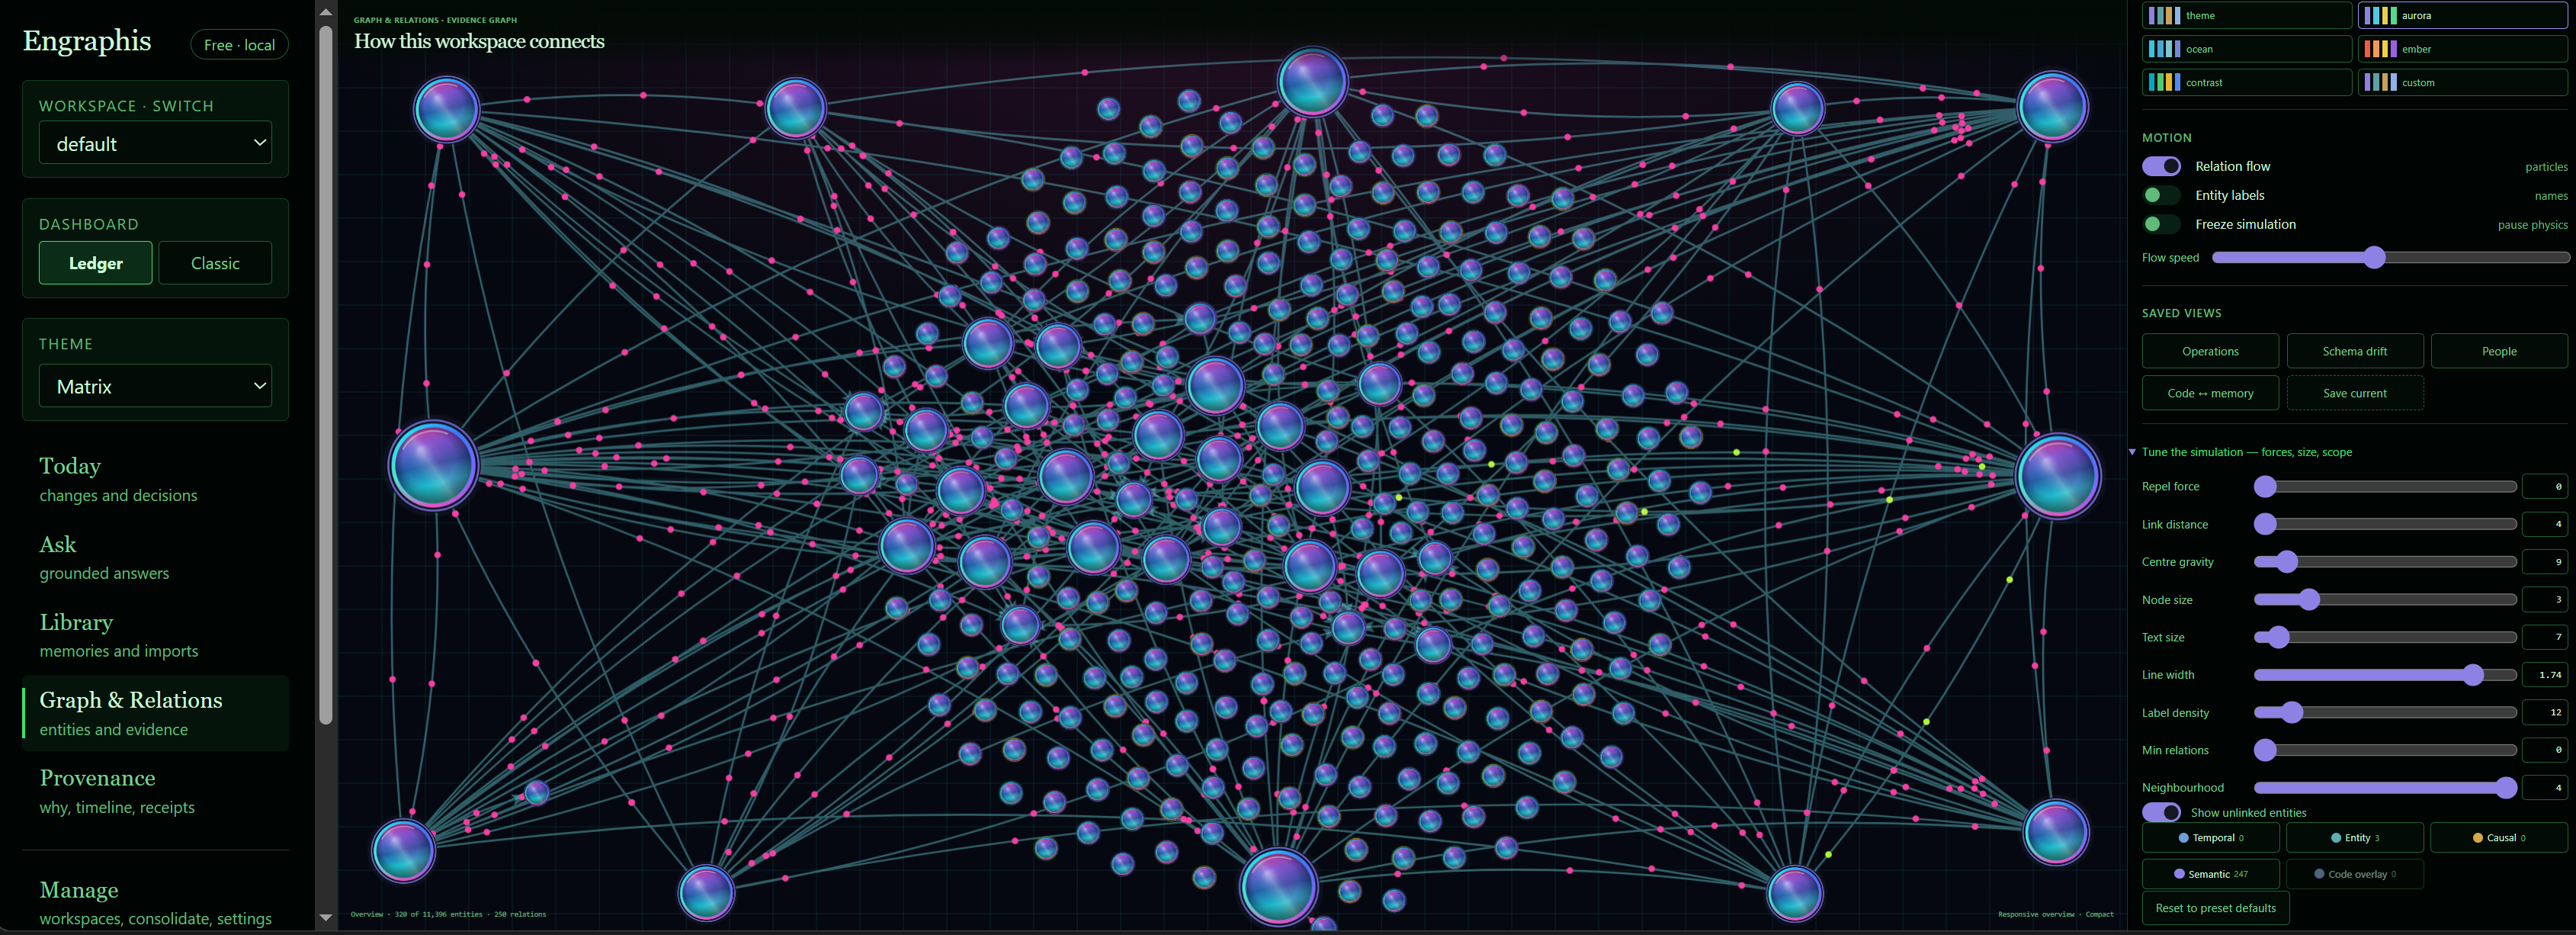
Explore memories and their relationships in the local dashboard.
The full local application requires Python 3.10 or newer. The NumPy-only core supports Python 3.9+.
python -m pip install "engraphis[all]"
engraphis-dashboard
The dashboard opens at http://127.0.0.1:8700. Local use needs no cloud account or API key.
To use the Python service directly:
from engraphis.service import MemoryService

memory = MemoryService.create("engraphis.db")
memory.remember("Auth migrated from JWT to PASETO.", workspace="acme", repo="api")
hit = memory.recall("Why did we change auth?", workspace="acme", repo="api")
print(hit["context"])
Connect a coding agent over MCP with the agent setup guide.
- Continuity: Organize memories by workspace, repository, and session, with a last-session handoff.
- Useful recall: Combine vector, lexical, graph, and code-aware retrieval, then pack results to a hard context budget.
- Grounded answers: Preserve provenance and temporal history; cite support or abstain when it is insufficient.
- Operator control: Keep the core local and offline-capable, with explicit controls for hosted services and external LLM providers.
The current registered artifact contains three deterministic offline fixture runs. It separates context size, retrieval quality, and grounded decision checks; these small fixtures do not establish general task performance.
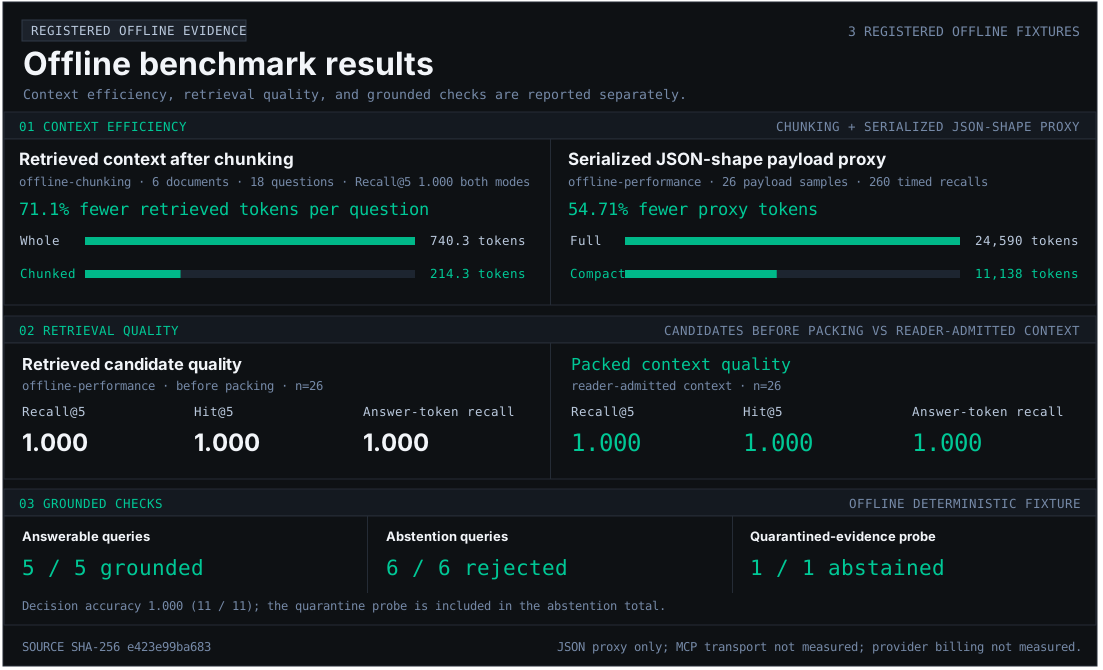
Three offline fixtures separate context reduction, candidate and packed retrieval quality, and grounded behavior. The chart shows the artifact checksum prefix; see the benchmark guide for the full checksum and reproduction steps.
| Fixture | Result | Quality check |
|---|---|---|
| Structure-aware chunking | Mean retrieved top-5 context: 740.3 → 214.3 tokens per question (71.1% lower, 18 questions) | Recall@5 = 1.000 in both modes |
| Recall payload proxy | JSON-shape proxy: 24,590 → 11,138 tokens (54.71% lower, 26 samples; 260 timed recalls) | Candidate and packed Recall@5, Hit@5, and answer-token recall are each 1.000 |
| Grounded decisions | 5/5 answerable queries grounded; 6/6 abstention queries rejected, including 1/1 quarantined-evidence check | 11/11 decisions correct |
The payload figure is a serialized JSON-shape estimate, not an MCP transport measurement or provider billing total. See the Benchmark methodology for artifact identity, counting methods, reproduction commands, external-evaluation boundaries, and limitations.
Use Review with Jev in the local dashboard to check whether selected evidence can answer a question or compare two memories for a possible contradiction. Remote review sends only selected, bounded excerpts and the supplied question after per-call consent and public or internal classification. Secret, malformed, and unknown sensitivity classifications are blocked. The existing MCP decision tool handles command and completion reviews.
Recall route selection is experimental and BYOK-only. Smart MCP opts in through engraphis_recall_context with allow_remote=true and a public or internal classification. Classic MCP also requires planning="auto" and jev_assisted=true. Jev receives the original query and bounded deterministic routes, not recalled memory bodies; it cannot change scope, time, type, or trust filters. Local behavior is the default. Uncertain, malformed, or failed requests fall back to deterministic behavior. Jev cannot write memories, change grounded-recall requirements, authorize commands, or certify completion. Direct BYOK use may incur provider charges.
Jev-assisted recall planning is experimental. In an exploratory comparison using 40 public synthetic tasks, Jev selected a route on all 40 calls but did not change nDCG@5, Recall@5, or answer-token coverage. This fixture does not establish a benefit on held-out user workloads, so no retrieval-quality improvement is claimed.
Managed Jev is currently not_yet_available pending release acceptance and
service-capacity qualification; client configuration does not enable it. After
enablement, every legitimate Pro user and each eligible Team named seat, including paid
viewers, with an active paid, trial, or test entitlement receives managed Jev at no
additional customer charge and without a personal provider key.
Each individual receives all three independent rolling limits: 100 evaluated questions per rolling hour, 1,000 per rolling five hours, and 2,000 per rolling 24 hours. Usage is per person, not pooled across a Team and not monthly. Each evaluated question counts once; if a batch is evaluated, every question counts, and command review evaluates two questions. Admitted attempts that fail or are interrupted remain counted. No overage is charged. The account portal reports each member's remaining usage across all three windows; usage returns as earlier questions leave each rolling window.
The existing production fleet guard remains 100 questions per day across the service. That limit conflicts with these per-person rolling caps and may pause or reject requests earlier. Resolve capacity and the fleet guard before launch. The supported decisions are advisory; current synthetic fixtures do not demonstrate Jev accuracy or cost savings. See hosted plans and Jev details.
- Configuration reference
- MCP tool reference
- Agent and LLM provider setup
- Architecture and query planning
- Docker deployment
- Document import
- Cloud Sync
- Pi extension
- Memory write review
- Security policy
- Hosted plans and licensing
Engraphis is licensed under Apache-2.0. The license does not grant trademark rights. See LICENSE, NOTICE, and the licensing guide. The hosted control plane and managed services are private services.