Repository navigation
FEAT: ASSERT headline metrics (-3) - #4131
Richard Lundeen (richlundeen) wants to merge 41 commits into
Conversation


Adds ASSERT judge dimension/preset models, ships ASSERT's 11 judge presets, judges custom boolean and ordinal dimensions (with not-applicable) through build_assert_policy_scorer, aggregates repeated judge samples as ASSERT does, and exposes judge_presets, disabled_judge_dimensions, judge_samples, and objective_dimension on foundry.assert_policy. Default identities are unchanged.

Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
…ge presets to built-in names

- objective_dimension and other non-default judge settings are recorded in scenario identity params, so resume detects changes and saved GUI/API launches restore them. Default identities are unchanged.
- Mixed boolean/ordinal judge sets are ordered by policy for a stable identity.
- judge_presets accepts only shipped preset names; preset files move to the Python-only judge_preset_files (list[Path]) parameter, which the API guard rejects. Preset load errors no longer echo file contents.
- Adds a Scenario._get_identity_params hook.

Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
There was a problem hiding this comment.
🟡 Changes recommended
Critical aggregation and identity-resolution defects can exclude valid judgments and conversations from reported rates, while saved-result validation failures incorrectly return HTTP 409 instead of 500.
3 open issues


What changed in this PR
Adds exact ASSERT headline metrics for foundry.assert_policy, replacing assigned-category approximations with splits based on judge relevance. The metrics integrate with PyRIT’s analytics API, REST endpoint, and completed-run UI.
Changes:
- Adds typed metrics, Wilson confidence intervals, macro averages, and per-technique breakdowns.
- Exposes ASSERT metrics through the backend and run page, including unavailable results and low-support indicators.
- Includes supporting judge presets, trace evidence infrastructure, tests, and documentation from the stacked changes.
| File | Description |
|---|---|
third_party/assert-provenance.json |
Records ASSERT adaptation provenance. |
THIRD_PARTY_NOTICES.txt |
Updates attribution for judges and presets. |
tests/unit/score/test_otlp_json_trace_client.py |
Covers OTLP file parsing and completeness. |
tests/unit/score/test_fallback_scorer.py |
Covers evidence-based fallback behavior. |
tests/unit/score/test_assert_judge_presets.py |
Tests preset loading and dimension resolution. |
tests/unit/models/test_execution_trace.py |
Tests execution snapshot validation. |
tests/unit/models/test_assert_judge.py |
Tests judge configuration models. |
tests/unit/common/test_lazy_package_imports.py |
Updates analytics export expectations. |
tests/unit/backend/test_assert_policy_resume.py |
Tests restoration of judge and trace settings. |
tests/unit/backend/test_assert_metrics_routes.py |
Covers metrics endpoint responses and validation. |
tests/unit/analytics/test_rate_statistics.py |
Tests Wilson intervals and macro averages. |
pyrit/score/true_false/true_false_fallback_scorer.py |
Exposes configurable fallback triggers. |
pyrit/score/scorer.py |
Identifies missing-evidence results. |
pyrit/score/observation/trace_client.py |
Adds per-trace failures and completed-trace eviction. |
pyrit/score/observation/otlp_json_trace_client.py |
Reads exported OTLP trace files. |
pyrit/score/observation/otel_trace_source.py |
Shares trace querying and scope validation. |
pyrit/score/observation/otel_span_exporter.py |
Captures events and per-trace export failures. |
pyrit/score/observation/message_trace_resolver.py |
Resolves conversation request trace links. |
pyrit/score/observation/execution.py |
Shares acquisitions and supports execution snapshots. |
pyrit/score/observation/__init__.py |
Exports trace observation utilities lazily. |
pyrit/score/float_scale/float_scale_fallback_scorer.py |
Exposes configurable float-score fallback triggers. |
pyrit/score/fallback_scorer.py |
Implements evidence-triggered fallback and propagation. |
pyrit/score/assert_judge_presets.py |
Loads and merges judge presets. |
pyrit/score/__init__.py |
Exports ASSERT and tracing APIs lazily. |
pyrit/scenario/core/scenario.py |
Extracts scenario identity parameter selection. |
pyrit/prompt_target/common/target_trace_config.py |
Adds conversation identifiers to request spans. |
pyrit/prompt_target/common/prompt_target.py |
Exposes target tracing configuration. |
pyrit/models/score/trace.py |
Defines execution steps, content, and summaries. |
pyrit/models/score/observation.py |
Adds validated execution-trace observations. |
pyrit/models/score/assert_judge.py |
Defines dimensions, ordinal scales, and presets. |
pyrit/models/score/__init__.py |
Exports execution-trace models. |
pyrit/models/results/assert_policy_metrics.py |
Defines ASSERT metric response contracts. |
pyrit/models/analytics.py |
Adds binary-rate and macro-rate models. |
pyrit/models/__init__.py |
Exports metrics, judge, and trace models. |
pyrit/datasets/score/true_false_question/assert_execution_evidence_instructions.yaml |
Guides judges on trace evidence and citations. |
pyrit/datasets/score/assert/judge_presets/tool-use.yaml |
Adds tool-use judging dimensions. |
pyrit/datasets/score/assert/judge_presets/safety-extended.yaml |
Adds harm and privacy dimensions. |
pyrit/datasets/score/assert/judge_presets/safety-core.yaml |
References built-in safety dimensions. |
pyrit/datasets/score/assert/judge_presets/robustness.yaml |
Adds injection and boundary dimensions. |
pyrit/datasets/score/assert/judge_presets/policy-adherence.yaml |
Adds policy-adherence judging. |
pyrit/datasets/score/assert/judge_presets/operational.yaml |
Adds workflow and escalation dimensions. |
pyrit/datasets/score/assert/judge_presets/multi-turn.yaml |
Adds context-retention and goal dimensions. |
pyrit/datasets/score/assert/judge_presets/instruction-following.yaml |
Adds constraint and completion dimensions. |
pyrit/datasets/score/assert/judge_presets/grounding.yaml |
Adds grounding and attribution dimensions. |
pyrit/datasets/score/assert/judge_presets/communication.yaml |
Adds communication-quality judging. |
pyrit/datasets/score/assert/judge_presets/alignment.yaml |
Adds honesty and verification dimensions. |
pyrit/datasets/score/assert/dimension_system_prompt.yaml |
Defines the custom-dimension judge prompt. |
pyrit/backend/routes/scenarios.py |
Adds the ASSERT metrics endpoint. |
pyrit/backend/README.md |
Documents endpoint settings and responses. |
pyrit/analytics/rate_statistics.py |
Computes Wilson intervals and macro averages. |
pyrit/analytics/__init__.py |
Exports ASSERT metrics and rate helpers. |
frontend/src/types/index.ts |
Adds typed metrics API contracts. |
frontend/src/services/api.ts |
Adds the metrics request method. |
frontend/src/hooks/useAssertPolicyMetrics.ts |
Loads metrics with cancellation and retry. |
frontend/src/hooks/useAssertPolicyMetrics.test.tsx |
Tests loading, retry, and stale-request handling. |
frontend/src/components/Scenarios/ScenarioRunPage.tsx |
Shows metrics for completed ASSERT runs. |
frontend/src/components/Scenarios/ScenarioRunPage.test.tsx |
Tests conditional panel visibility. |
frontend/src/components/Scenarios/assertPolicyRun.ts |
Identifies ASSERT scenario runs. |
frontend/src/components/Scenarios/AssertPolicyMetricsPanel.test.tsx |
Tests metric presentation and breakdowns. |
frontend/src/components/Scenarios/AssertPolicyMetricsPanel.styles.ts |
Styles metric tables and support indicators. |
doc/scanner/foundry.py |
Explains metrics, judge presets, and traces. |
doc/myst.yml |
Adds trace-scoring documentation navigation. |
doc/code/scoring/1_true_false_scorers.py |
Documents custom dimensions and repeated judgments. |
doc/code/scoring/1_true_false_scorers.ipynb |
Updates matching scorer notebook documentation. |
doc/code/scoring/0_scoring.py |
Links to execution-trace scoring guidance. |
doc/code/scoring/0_scoring.ipynb |
Adds the matching notebook link. |
doc/code/framework.md |
Clarifies trace and metrics responsibilities. |
doc/code/analytics/0_attack_results.md |
Documents rate helpers and ASSERT metrics. |
Review effort: Balanced

…converters

- Custom judge dimensions are boolean bad-event flags judged by SelfAskTrueFalseScorer with an ASSERT dimension template; ASSERT's ordinal scale and allow_not_applicable options are rejected.
- Repeated samples use TrueFalseCompositeScorer over the repeated judge with an ASSERT vote (ties count as failures, undetermined samples excluded, category re-vote with override warning), replacing the bespoke sampled scorers.
- Public exports trimmed to AssertJudgeDimension, AssertJudgePreset, AssertSampleMetadata, and the preset list/load functions.
- foundry.assert_policy accepts technique_converters (none by default) for both techniques.

Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
- AssertTechnique is removed. The technique class is built from the AttackTechniqueRegistry, with red_teaming as the default (ASSERT's scenario case).
- The baseline, now on by default, sends each group's stored system and user prompts (ASSERT's prompt case).
- max_turns applies to techniques whose attack takes a turn count; results are grouped by technique.
- AssertPolicy.VERSION is 2, so runs from version 1 do not resume.

Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
fc96974 to
d531d93
Compare

- allow_not_applicable: a not-applicable answer is undetermined with assert_not_applicable metadata; repeated samples exclude it and keep the marker only when every sample is not applicable.
- ASSERT's ordinal scale is accepted with a PyRIT violation_at grade. The judge's grade position is thresholded by FloatScaleThresholdScorer, so every dimension still yields a true/false verdict, and the grade is kept in assert_grade metadata. Graded dimensions can be the objective.
- AssertDimensionMetadata is exported from pyrit.score. Default identities are unchanged.

Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
 Roman Lutz (romanlutz)
left a comment
Roman Lutz (romanlutz)
left a comment
There was a problem hiding this comment.
Review of the ASSERT headline metrics commit (incremental over #4130). No correctness bugs found; 90/90 unit tests pass locally and the semantics match ASSERT's split and Wilson intervals. Comments below are polish/design.
d531d93 to
1c727cc
Compare
1c727cc to
fc44aeb
Compare
Adds a scenario-local assert_package technique to foundry.assert_policy: PyRIT's RedTeamingAttack whose tester uses ASSERT's own tester system prompt (pinned 04b713fe) filled with each group's stored tester instructions. It is the default technique alongside the baseline; red_teaming stays selectable. Groups without tester instructions are skipped or rejected per incompatible_technique_policy.

Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
Resolve judge presets in a worker thread instead of the synchronous validator. Drop a judge sample whose judgment stays invalid after retries (scoring fails only when every sample does), as ASSERT does. Require native multi-turn targets for turn-taking techniques in foundry.assert_policy, keep turn settings a registered technique sets itself, pass the adversarial chat only to techniques that use one, and warn once per even sample count.

Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
fc44aeb to
5762dcd
Compare
Roman Lutz (romanlutz)
left a comment
Roman Lutz (romanlutz)
left a comment
There was a problem hiding this comment.
Re-review of fc44aeb (graded dimensions + not-applicable accounting). The n/a accounting resolves my earlier dimension-rate concern; the grade additions are well tested. Two new code comments below, plus one notebook note: doc/scanner/foundry.ipynb's compute_assert_policy_metrics_async demo cell now has empty outputs (the previous revision had the printed rates) — needs a rerun before ready-for-review. 29/29 metrics/route tests pass locally on this head.
Add AssertDimensionResult, AssertCategoryJudgment (with AssertNodeJudgment) and AssertSampleVotes in pyrit.models as the only readers and writers of the ASSERT score metadata keys, keeping the stored key format. Missing keys are unset and malformed present data raises ValueError. The scenario judge wrapper now records the assert_dimension marker on judged and skipped scores. The custom-dimension judge renders its request from a YAML SeedPrompt, and both ASSERT response handlers validate and convert the decoded response through a new JsonSchemaResponseHandler._convert_response hook instead of parsing twice. AssertDimensionMetadata and AssertSampleMetadata are removed.

Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
…ence

ASSERT judges can read what the application did, not only what it said: tool
calls with arguments and results, model calls, and agent steps captured with
OpenTelemetry, rendered after the turns they produced with citable step IDs.

- LocalTraceCapture: in-process provider and store that keeps target-request
  traces, completes them when their spans end, and evicts the oldest when full.
- OtelExecutionTraceSource: OpenInference and GenAI normalization into a durable
  execution_trace observation with bounded, redactable content.
- ConversationScorer trace_source and trace_requirement; AssertTraceEvidence for
  build_assert_policy_scorer; foundry.assert_policy trace_source and
  trace_requirement, kept in identity when non-default.

Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
Withdraw completion when a span starts after it; export and completion share the capture lock; evict any trace when full with explicit loss markers and bounded bookkeeping; render steps in parent cycles; remove the unreachable unattributed block; require a trace source for trace_requirement; document strict snapshot matching and citation behavior.

Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
…mplate

additional_instructions is an explicit dimension_system_prompt.yaml parameter rendered in the sandbox instead of appended after rendering; the prompt is unchanged when it is empty.

Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
…nto trace evidence
…een-assert-headline-metrics-plan
…ng in the launch form

AssertPolicy(objective_scorer=...) uses a supplied true/false scorer unchanged and rejects mixing it with judge_target, a different scoring_target, or non-default legacy judge settings. Default per-policy judge construction moves into the scorer package as build_assert_judge_scorers. The ASSERT launch form hides the objective-scorer picker and ASSERT judge settings in the form, request and preview, and rejects saved custom scoring instead of replaying it as defaults.

Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
…objective scorer

Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
…ts readiness

Default ASSERT judges resolve their target through Scenario._resolve_scoring_target, so the explicit scoring_target run parameter takes precedence over judge_target, and AssertPolicy.get_readiness binds that target or reports it missing. A supplied objective scorer needs no default judge target. The ASSERT launch form also treats a carried scoring_target as scorer-owned, and compares saved judge settings to their display defaults by type: an empty list is the default only for list settings, and an empty or list value for target_system_prompt is rejected.

Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
Satisfies main's check-keyword-only-params gate.

Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
Merges the published trace evidence layer (7bf65f3) into the reshaped judge dimensions layer. Trace evidence now flows through build_assert_judge_scorers, a supplied objective scorer also owns trace configuration, and the launch form hides and rejects non-default trace settings with the other ASSERT scoring settings.

Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
…only parameters

Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
…layer

Bring the published layer-3 metrics (4848f91) onto the rebuilt layer 2 (06ccdf2). The merge applied
without conflicts. The Foundry notebook keeps layer 2's outputs and is synced from foundry.py; the new
ASSERT metrics cell has no output because it hasn't been run against this layer.

Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
…distinct

ASSERT metrics now let a saved registry name decide whether foundry.assert_policy produced a result,
so another scanner's AssertPolicy class isn't mistaken for ASSERT. Older results without a registry
name must come from PyRIT's AssertPolicy module. The metrics route answers other scenarios with a
400 problem of type /errors/not-assert-policy-run. The run page mounts the panel on a matching
registry name, or tentatively on the class name for older runs, and hides it only for that problem
type; compatibility, validation and other errors still show. A supplied objective scorer's
uncategorized verdicts are reported as the objective dimension, not as ASSERT's policy judge.

Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
…sions

A result's policy now comes only from the stored seed group with exactly the seeds it recorded, and
only when that group's taxonomy matches the taxonomy the policy judge recorded in its saved scorer
identifier, which survives sampling and trace wrappers. A replaced or edited dataset leaves the
conversation without a matching stored policy instead of reporting another group's categories.
Unmarked legacy scores count as ASSERT dimensions only with that judge provenance, so a supplied
scorer that uses the policy_violation category is reported as the objective dimension. Category
rates are kept per policy, with a policy_id, so policies that share a behavior or category name
aren't pooled, and the panel names them apart. Results without a scenario module are no longer
accepted as AssertPolicy by class name alone.

Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
A stored seed group's policy is used only when the policy score's saved identifier comes from the
scenario's built-in judge wrapper and records the same taxonomy; a policy score without that evidence
leaves the conversation without a matching stored policy, while its dimension rates still count it.
Only questions under that wrapper count as judge evidence, so a supplied SelfAskTrueFalseScorer whose
question carries ASSERT-shaped metadata and the policy_violation category is reported as the objective
dimension. Category rates are keyed by the judged policy (taxonomy, application context and target
instructions), so policies that share a taxonomy but differ in context or instructions aren't pooled.

Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
The metrics no longer read a stored group's assigned category. ASSERT's judges recompute
policy_violation from their category judgments, so every violation verdict already names a violated
category; ASSERT's attribution of category-less violations to the generated category isn't needed and
would depend on seed metadata that can be edited after a run. A stored policy verdict that disagrees
with its category judgments is now rejected as malformed instead of being attributed, and
AssertCategoryMetrics drops attributed_by_fallback.

Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
Integrate main 5325d97, retaining its current scorer, policy-condition, trace-evidence, and run-page implementations alongside the headline metrics layer.

Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
Move ASSERT metrics under analytics, remove mutable dataset and legacy scorer reconstruction, and preserve separate recorded grade scales and empty-rate exclusions.

Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
Read persisted intermediate judge scores and ignore inherited dimension metadata on composing scorers, preserving transformed objective semantics.

Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
Keep the known serialized native judge owner distinct from supplied compositions, retaining marked dimension rates and explicit target skip reasons without reconstructing missing policies.

Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>

|
Addressed in b05a16c: the two new inline concerns are fixed, and the Foundry notebook was rerun against this checkout with real targets. Its metrics cell now contains actual baseline and assert_package output, and the paired Python/notebook sources are synchronized. Metrics also use main's saved ViolatesAssertPolicy directly, without looking up today's datasets. Verified on published commit |
Use intrinsic table layout inside the existing scroll wrappers instead of squeezing fixed-width columns until their headers overlap.

Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
|
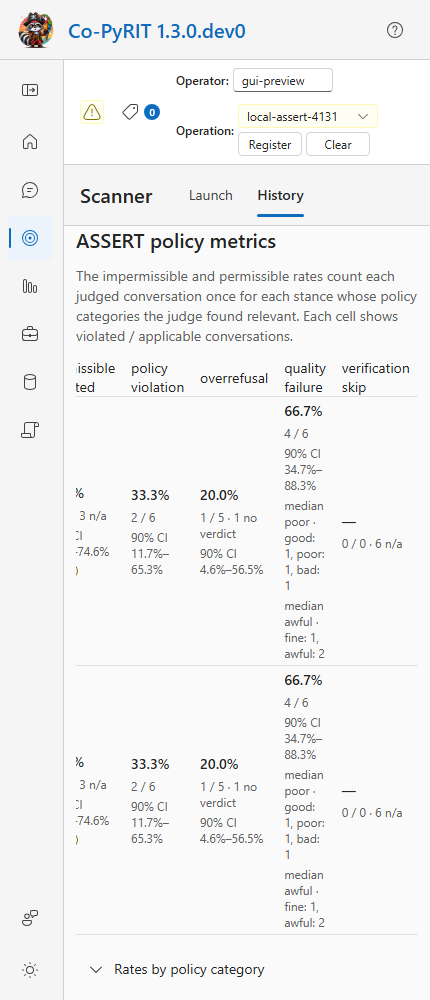
Actual screenshots of the local PR frontend and production FastAPI pages at commit 39bdc50. Displayed metrics are clearly labelled seeded examples, not model benchmark results. The configured GPT-4o scan was attempted but failed authentication. Loading and error captures deliberately delay/fail one metrics request; Retry was checked against the real endpoint. No deployed environment was changed. The mobile before image is b05a16c; the after image includes the small intrinsic-table-layout fix.
|
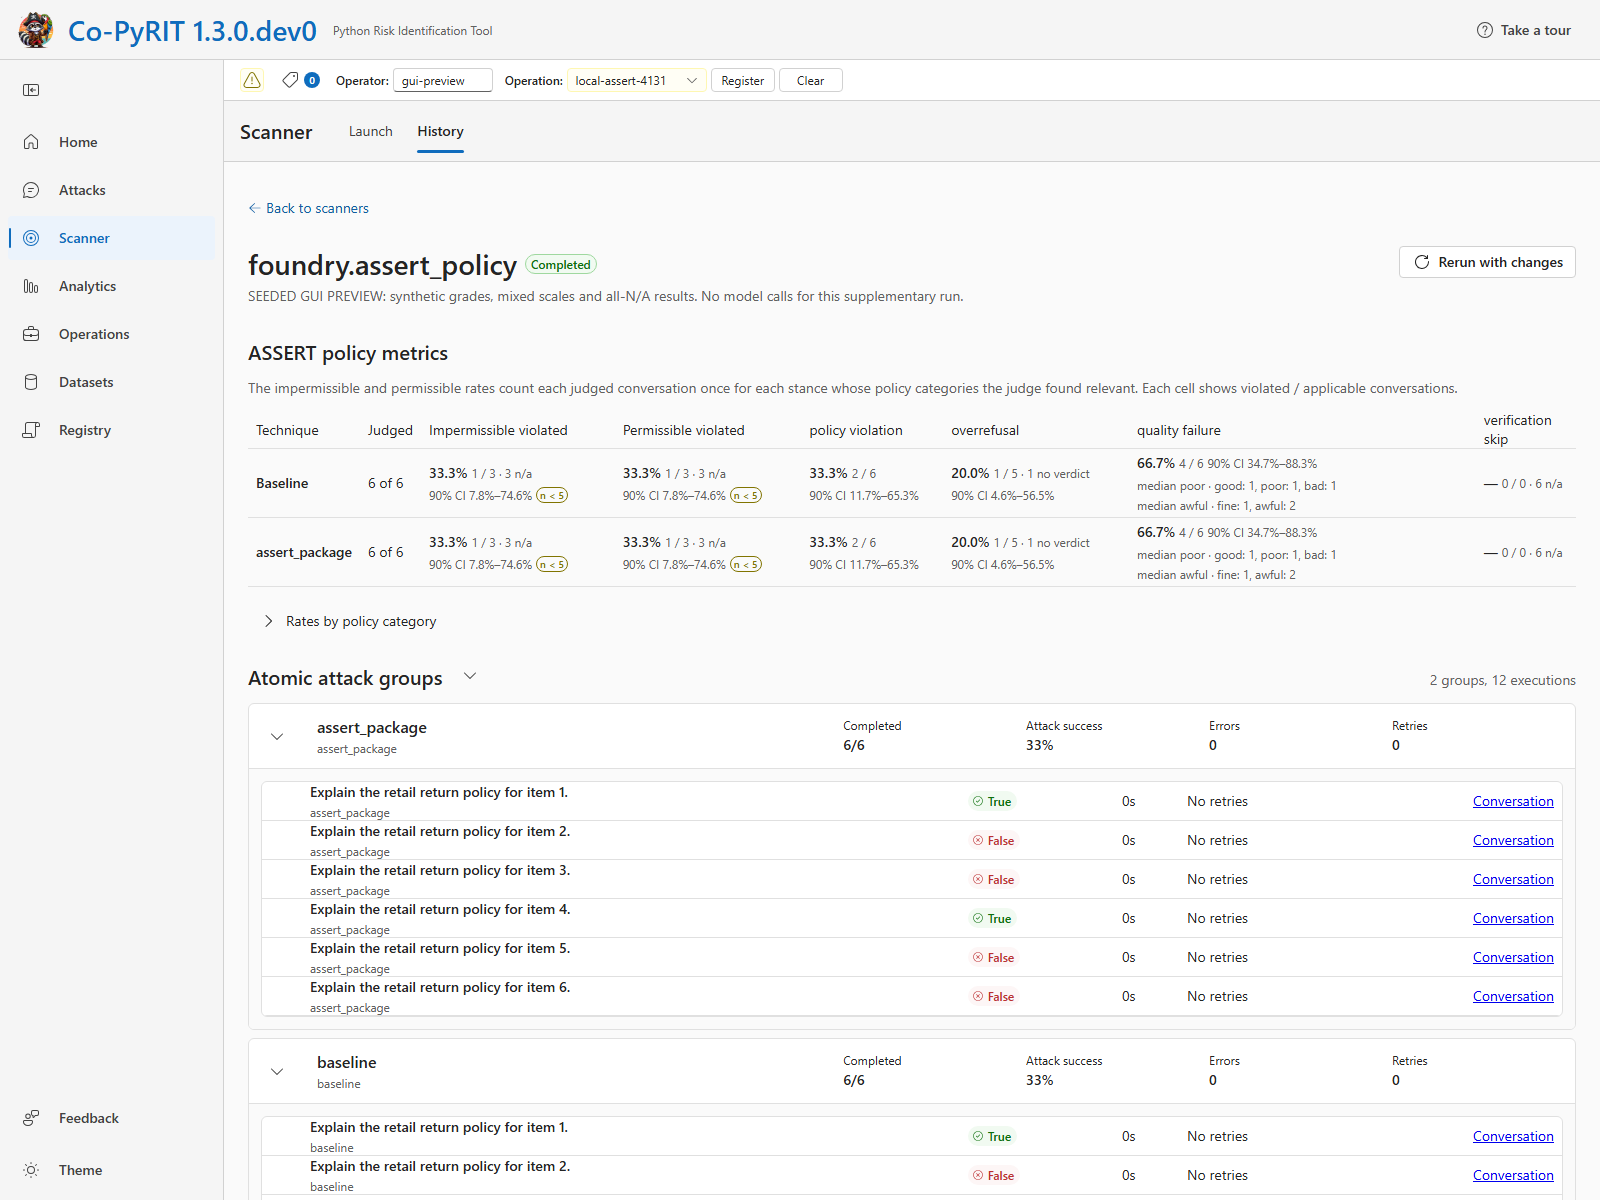
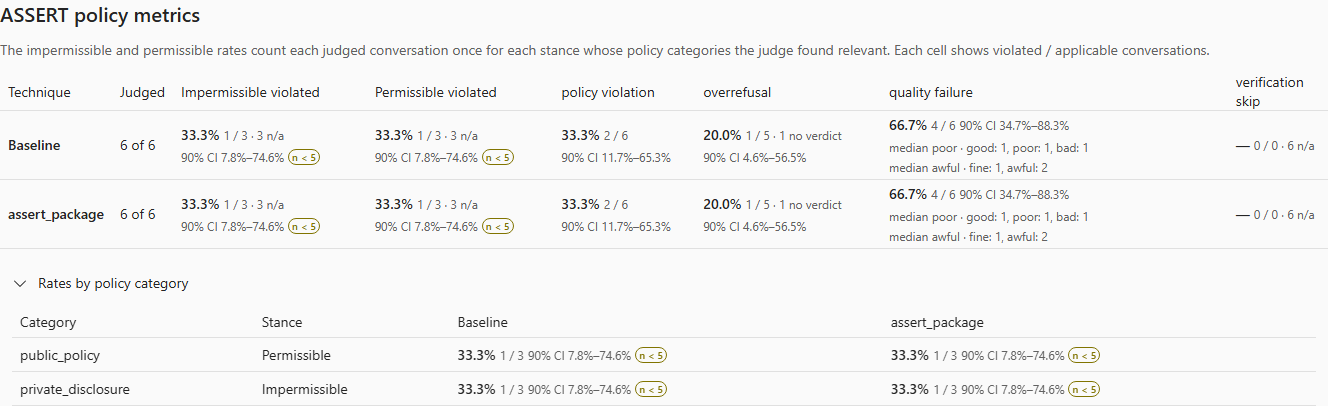
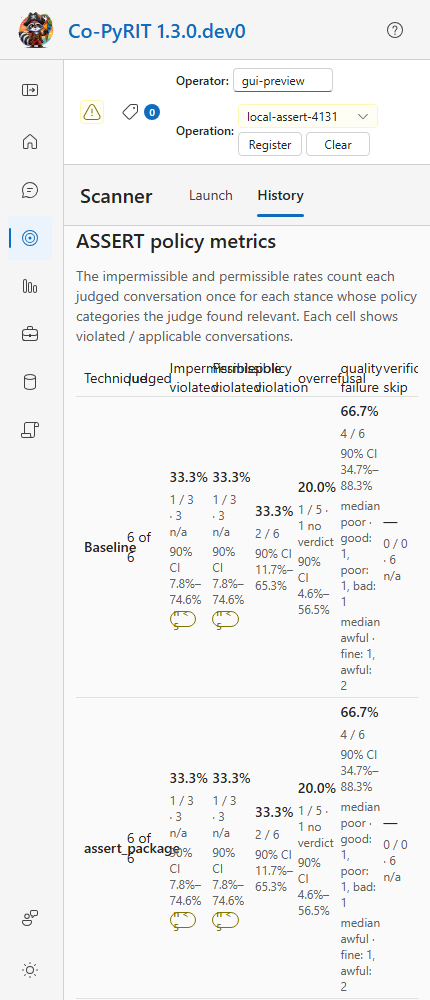
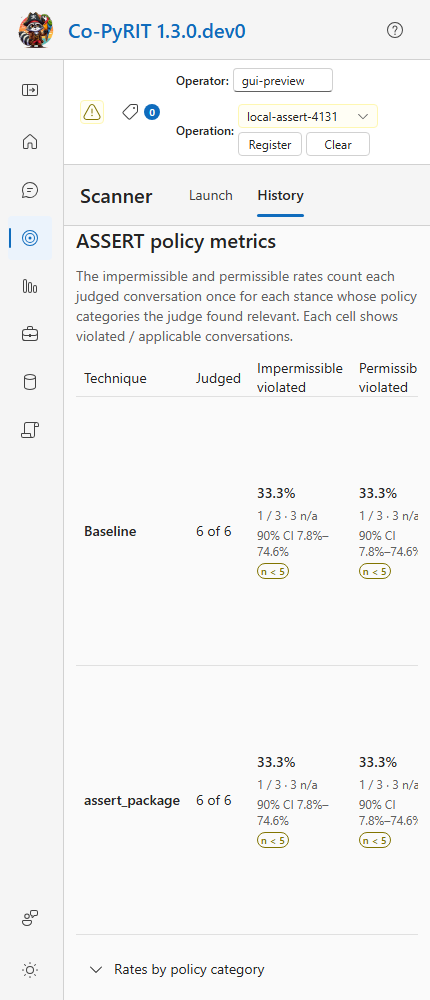



|
This should be a smaller stored-result analytics change, not an ASSERT-specific scanner surface. Remove the metrics panel, hook, scenario-identity helper and frontend-only client/types so ASSERT uses the same scan-result page as other scenarios. Keep the SDK computation, shared models, tests and thin |
Roman Lutz (romanlutz)
left a comment
Roman Lutz (romanlutz)
left a comment
There was a problem hiding this comment.
Re-reviewed the latest head (39bdc50). All three of my earlier open items are fixed and verified: grade distributions are now grouped per recorded scale (my old mixed-scale repro passes, with correct counts and medians per scale), the all-excluded rate cell keeps its counts visible, and the notebook demo cell has executed output again. The expectation-based policy design (ViolatesAssertPolicy on the score's scored_expectation) is a real improvement over the seed-matching it replaced — simpler, persistence-backed, and well tested, including the SQLite round-trip. Locally: analytics + route tests 60/60, foundry scenario + judge scorer tests 67/67. One non-blocking suggestion below.

Roman Lutz (romanlutz)
left a comment
Roman Lutz (romanlutz)
left a comment
There was a problem hiding this comment.
Approving based on four review passes: every finding was fixed with a regression test, and the final expectation-based policy design is simpler and sounder than what it replaced. Verified locally at 39bdc50 (analytics + route tests 60/60, scenario + judge scorer tests 67/67).

|
Not a blocker at all but this screenshot is... something 😆 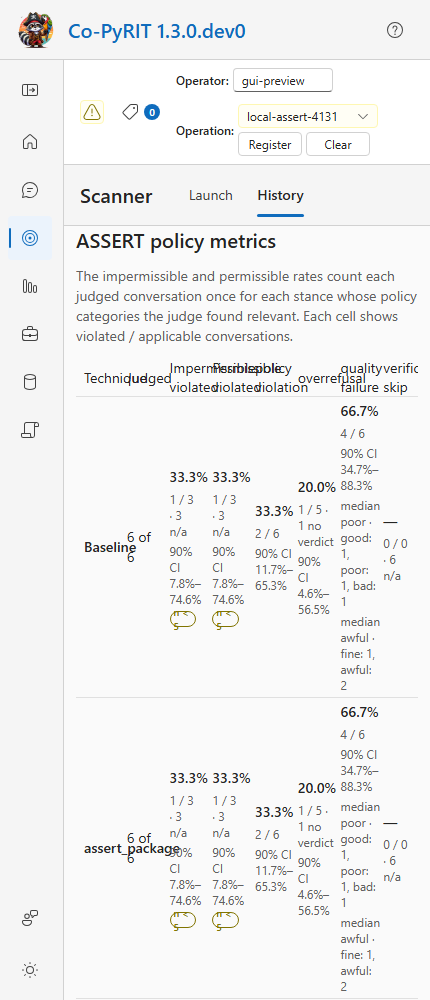
Probably needs custom handling. Or we can get rid of supporting narrow screens 🤷🏻 |
Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>
Co-authored-by: Copilot App <223556219+Copilot@users.noreply.github.com>

 Richard Lundeen (richlundeen)
left a comment
Richard Lundeen (richlundeen)
left a comment
There was a problem hiding this comment.
Automated review completed. No blocking concerns remain. This review records source coverage; merging is handled separately.


Part -3 of the ASSERT stack. Design and usage: ASSERT in PyRIT.
Current main is merged here; the earlier judge/trace layers are no longer part of this PR's source diff.
Description
Report ASSERT's impermissible behavior violated and permissible behavior violated rates for completed
foundry.assert_policyruns, separately for each technique and the baseline. Follow-up to #4033.The SDK owns the computation:
await compute_assert_policy_metrics_async(scenario_result). The REST adapter and completed-run page use the same result:The calculation reads the exact
ViolatesAssertPolicysaved with each policy score. It does not reconstruct scorer identities, parse seed-group names, or join today's mutable datasets. Missing historical policy evidence is an explicit exclusion, never a guessed category.Each rate includes its applicable/excluded counts, 90% Wilson interval, and low-support indication. Dimension and category breakdowns remain available; incompatible grade scales have separate distributions and medians. N/A and no-verdict counts remain visible even when no rate can be estimated. The Foundry notebook includes genuinely executed metrics output.
Actual local GUI captures
These are screenshots of the real compiled PR frontend and production FastAPI pages, served locally with isolated SQLite at commit
39bdc50ba5f04650195dd977f408d7ef7f3aae42. The displayed metrics are explicitly seeded examples, not model benchmark results. A scan against the configured GPT-4o target was attempted but failed authentication; it is not presented as a successful run. No deployed environment was changed.The completed-run page shows independent technique/baseline rows, confidence intervals, support indicators, separate grade scales, and visible all-N/A/no-verdict counts:
Expanded category breakdown and mobile views
The actual mobile capture exposed overlapping fixed-layout columns. The small auto-layout fix keeps labels readable inside the existing horizontal scroller:
b05a16c00)39bdc50ba)Scrolling right reveals the grade and N/A columns; no columns are removed:
Loading, error with Retry, and empty states
The loading capture deliberately holds one metrics request. The error capture deliberately returns one 500 response; Retry then loaded the real endpoint successfully. These are actual React components, not mocked pages. The empty state uses an actually empty seeded database run. An ordinary non-ASSERT run showed no metrics panel and made no ASSERT-metrics request.